The Sonic Alpha: Podcast Sentiment Scoring and the Systematic Quantification of Unstructured Audio Signals
TL;DR: The Vetta Framework
- Core Thesis: Podcast audio may become a useful unstructured-sentiment input only when systematic investors treat it as a signal-extraction problem, not a shortcut to narrative certainty. [24]
- Key Data Point: Research distinguishes structured from unstructured investor sentiment and finds that fluctuations in both are positively associated with market volatility. [24]
- Market Implication: The opportunity lies less in raw commentary than in repeatable pipelines that isolate speech, preserve provenance, measure context, and test incremental value. [7][24]
- Primary Risk: Audio-derived signals can be distorted by recording conditions, speaker identity, production choices, privacy concerns, and security exposure. [1][9][14]
- Action Signal: No ledger-supported public company, ticker, market capitalization, valuation, or listed-options pathway establishes a direct security-level trade on podcast sentiment scoring.
A podcast is often treated as a conversation preserved in digital form. For systematic investing, it is something more demanding: a stream of speech, pauses, emphasis, interruptions, production choices, and social cues, only some of which may matter economically.
That distinction is central; Research separating structured from unstructured investor sentiment finds that both relate negatively to market returns, while changes in both forms of sentiment are positively associated with market volatility. [24]
The same research finds that the volatility effect associated with unstructured-sentiment fluctuations becomes more pronounced as the share of noise traders increases. [24] This does not mean every spoken opinion forecasts a tradeable market move. It suggests that loosely organized expression may matter when attention, belief, and feedback loops become unusually important.
Research on podcasting identifies flexibility, customization, specialization, interactivity, and adaptive monetization as features attracting listeners from traditional radio. [11] Those characteristics can also create fragmentation, because different incentives, editorial standards, production styles, and degrees of expertise may coexist within the same broad audio category.
The investment question is therefore not whether audio can contain emotion or opinion; The harder question is whether a disciplined process can separate economically meaningful conviction from promotion, repetition, irony, performance, ambient mood, and ordinary conversational noise.
The useful metaphor is a mixing desk. Raw audio arrives through overlapping channels, and the researcher must first isolate speech from music, advertising, crosstalk, and room sound; then identify who spoke; then interpret what was said and how it was said; then test whether the resulting score adds information after text, market data, and structured sentiment have already been considered. [7][24]
What emerges is not a simple “podcast trade;” It is a research program in signal hygiene, model governance, and intellectual restraint.
The Landscape
Podcasting sits where media, identity, technology, and participation meet. Its appeal rests partly on flexible listening, specialized subject matter, and formats that can adapt to digital engagement more readily than legacy radio. [11] That makes the medium relevant to researchers seeking naturally occurring speech beyond formal earnings calls, scripted news reports, or standardized disclosures.
Yet openness creates an immediate data problem; A single episode may contain host commentary, guest testimony, advertisements, archival clips, prepared narration, spontaneous banter, music, and audience prompts. A digital file is not automatically a stable measurement object.
This is why podcast sentiment should not be framed as an audio version of a headline scanner. Text systems generally begin with a document boundary and a relatively clean linguistic unit. Audio systems begin earlier, with acoustic conditions that can alter apparent meaning before language analysis begins.
The relevant investment category is unstructured audio intelligence, not podcast popularity. That category may include spoken words, delivery, timing, speaker relationships, and contextual metadata, but only when those features can be processed consistently and tied to a specified economic hypothesis. [24]
The available evidence shows that sound is treated as a technical sensing modality in settings far removed from media. Researchers have examined sound-signal approaches for recognizing bolt loosening, while other work concerns low-frequency underwater sound detection and intelligent recognition. [2][8] These studies do not validate podcast alpha. They show that sound can become a structured analytical input when the target event and measurement objective are clearly defined.
Podcast sentiment is harder because its subject is semantic and social. A bolt may be loose or secure. A guest’s phrase may be optimistic, sarcastic, conditional, strategic, or simply vague.
Market relevance adds another layer; It may depend on who spoke, what listeners already believed, whether an episode was edited, and whether the topic was already reflected in prices. The audio file preserves the sound, but it does not settle the interpretation.
Research on social podcasting centers varying levels of audience participation in the medium. [22] That matters because a podcast can be part of an interactive chain rather than a one-way publication. Audience response may amplify an idea, but amplification is not the same as informed investor conviction.
Spatial-audio research sharpens this concern; Research on radio and podcast production notes revived interest in immersive and three-dimensional sound while identifying barriers to its wider use in factual programming. [9] Audio design is not neutral packaging; it may alter salience, immersion, and emotional force.
For systematic investors, this means a transcript is necessary but not sufficient. It captures lexical content. It does not fully preserve the production and delivery conditions that may shape how language is received.
KEY TAKEAWAY: Podcast sentiment is best understood as a high-dimensional research input whose value depends on separating economically relevant information from media noise. [9][11][24]
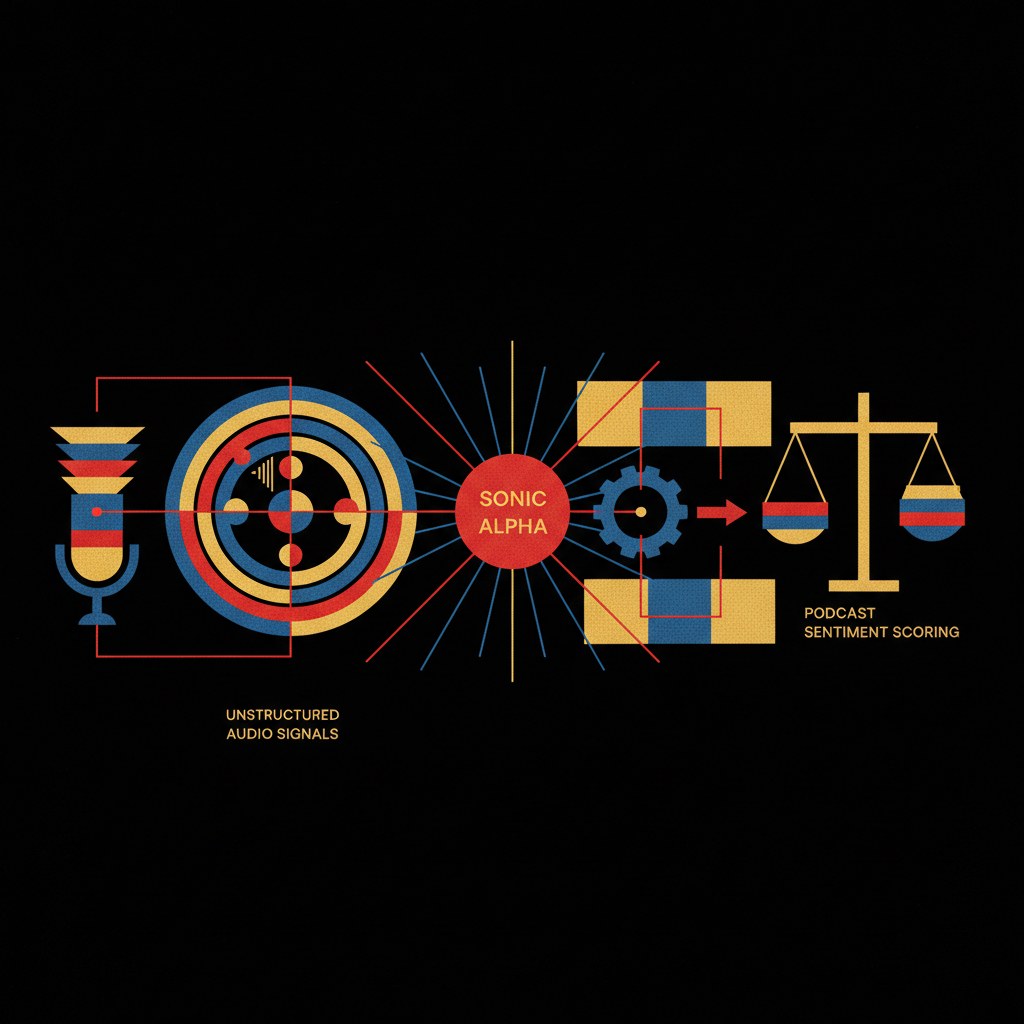
Editorial figure: The report's scale and Why Now argument rendered as a visual framework; the illustration provides context and does not represent measured data.
The Technology Deep Dive
A workable podcast-sentiment system begins with an uncomfortable premise: there is no single “audio signal;” There is only a recording containing many possible sources of variation. The first task is deciding what belongs in the model and what must be excluded.
At the front of the pipeline sits ingestion. This stage can capture audio files and available metadata, such as episode titles, publication sequence, show identity, guests, and broad topic labels. The ledger does not establish a universal podcast metadata standard, so metadata quality should be treated as a variable requiring audit rather than an assumption.
Next comes segmentation; Long-form episodes need division into meaningful units: speakers, turns of speech, topic changes, advertising breaks, music, and non-speech material. This is where a seemingly simple score can become misleading.
If a bullish advertisement is assigned to a cautious host, the downstream model may remain technically sophisticated while becoming economically useless. If a guest quotation is confused with a host’s own view, provenance fails before sentiment analysis begins. The pipeline must therefore preserve uncertainty surrounding every classification decision.
Google Research’s work on contrastive neural audio separation supports the narrower point that disentangling components within recordings is a distinct technical task; [7] The ledger does not establish that this work solves podcast transcription or finance-specific inference. It does establish that source separation deserves more respect than a preprocessing footnote.
A systematic workflow should keep this layer observable. It should retain confidence measures for speaker turns, flag difficult segments, and preserve links between outputs and source timestamps. Without traceability, a sentiment score becomes a sealed verdict with no practical route for error analysis.
The next layer concerns speech representation; Spoken language can be converted into text, while delivery may be represented through features such as pace, pauses, pitch movement, energy, overlap, and hesitation. These features are tempting because they seem to reach beyond ordinary text analysis.
Temptation is not proof. Rapid delivery could reflect excitement, anxiety, host style, editing, a constrained segment, or poor recording quality. A pause could represent caution, theatrical timing, a remote-connection delay, or interruption.
The model must demonstrate incremental predictive value rather than aesthetic novelty; That requirement is especially important when importing ideas from more bounded sound-recognition settings. Research on bolt-loosening recognition and low-frequency underwater detection addresses comparatively defined detection problems. [2][8]
Those studies support the proposition that sound can encode measurable conditions. They do not establish that prosody in a market podcast maps cleanly to future prices, returns, volatility, or factor performance. Human language remains a moving target because its meaning is shaped by context, incentives, and listener interpretation.
The language-understanding layer should score more than generic positivity; It may examine directional language, certainty, uncertainty, topic relevance, causal claims, and references to companies, sectors, or macroeconomic mechanisms. A useful system must distinguish “I like this company” from “new information changed my estimate.”
It must also distinguish broad optimism from security-level conviction. A speaker may praise innovation while remaining bearish on a company’s valuation. Another may criticize a business while arguing that the market already discounts the problem.
The correct target is economically contextual sentiment; A model that collapses these distinctions into a single positive-negative scale risks measuring tone rather than thesis. That risk may become larger when entertainment incentives reward expressive language.
The investor-sentiment research provides a theoretical anchor. Structured and unstructured sentiment are distinct components with different driving factors, and the cited work identifies relationships among sentiment, returns, and volatility. [24] Podcast scoring should therefore sit beside established inputs, not present itself as a replacement for structured data.
A further stage assigns provenance; The source of a statement matters as much as the statement itself. A host, guest, advertiser, journalist, founder, academic, and anonymous caller may speak under very different incentives.
The ledger does not provide a verified taxonomy of financial-podcast speakers. A production system would therefore need to build and test its own categories rather than infer authority from familiarity alone. Recognition is not the same as credibility, and prominence is not the same as predictive usefulness.
This layer should also identify repeated appearances and syndication; A view repeated across many shows may appear to be broad corroboration when it is actually one source moving through several microphones. The model must distinguish independent confirmation from audio echo.
Aggregation follows. Episode-level features may become show-level, topic-level, speaker-level, sector-level, or time-window measures. Each decision changes the economic meaning of the score.
A daily measure may appear responsive but magnify noise; A monthly measure may be steadier but too slow for shorter-horizon decisions. Aggregation should follow the hypothesis rather than precede it.
If the hypothesis concerns retail attention, an audience-facing measure may be appropriate. If it concerns expert disagreement, dispersion among identified speakers may matter more than average tone. If it concerns changes in perceived macro risk, abrupt shifts in language or confidence may be more useful than absolute sentiment.
Validation is where many appealing narratives should fail; A model needs a predeclared target, time-respecting splits, out-of-sample testing, and controls for information already visible in text, market data, or other sentiment measures. The ledger supports the relevance of unstructured sentiment to volatility-related research, but it does not establish any podcast-specific performance result. [24]
The decisive question is incremental contribution. Does audio add explanatory or predictive content after a transcript-only model? Does it add value after structured sentiment variables? Does it survive across market conditions?
A careful design would also test whether the result remains after excluding the largest shows, best-known speakers, or most heavily edited productions. A signal concentrated in one recognizable voice may be a fragile media artifact rather than a durable investment input.
Deployment introduces another discipline. A score should not enter a portfolio merely because it performs well in a historical exercise. It needs latency rules, source-quality thresholds, revision handling, model-drift monitoring, and procedures for investigating abnormal outputs.
Audio files can be corrected, re-uploaded, clipped, or distributed unevenly; A live system must know which version it heard and when it heard it. The file itself is part of the data lineage.
Security belongs within that governance structure. Kaspersky has described InjectEave as an attack that intercepts analog audio signals. [1] The ledger does not connect that attack to podcast-investment systems, but it demonstrates a broader principle: audio is not merely content; it can also be an attack surface.
Privacy requires similar care; Research on immersive audio identifies privacy, accessibility, and psychological impact among the ethical considerations surrounding advanced audio design. [14] A platform that treats voices as extractable data must distinguish public availability from unrestricted behavioral inference.
The mixing desk metaphor returns here. Separation is the fader. Transcript analysis is the equalizer. Provenance is the channel label. Validation is the sound check, and portfolio implementation is the final output level.
If one control is mis-set, the signal can become louder without becoming clearer.
Market Implications
The market implication of podcast sentiment is not that audio will displace financial statements, estimates, or prices. Its more plausible role is as a supplementary measure of belief formation, narrative propagation, and uncertainty.
That role becomes interesting where conventional data may capture language slowly. Corporate filings describe events that have already occurred. Structured surveys impose fixed questions.
Podcast discussion may reveal what participants are beginning to emphasize before that emphasis hardens into formal consensus. This possibility fits the distinction between structured and unstructured sentiment. [24]
Structured sentiment reflects more identifiable drivers and standardized expressions, while unstructured sentiment reflects less constrained forces in the cited framework; [24] A carefully built audio measure could sit closer to the latter category when it captures spontaneous discussion rather than prepared remarks.
Still, earlier information is not automatically better information. Early narratives can be incomplete, biased, or wrong. In markets, premature stories may increase volatility rather than generate alpha.
The practical value may therefore lie in detecting changes, not declaring truths; A sharp rise in topic intensity, uncertainty words, disagreement, or speaker overlap might flag an emerging narrative regime. That flag could inform research prioritization, liquidity assumptions, or risk budgeting without forcing an immediate directional trade.
Podcasting’s flexibility, specialization, and interactive potential make this use case plausible. [11] A specialized program may concentrate discussion around a narrow subject before that subject becomes a broad media keyword. Yet specialization can also create insularity, allowing a community to reinforce its own priors.
A systematic investor should therefore measure concentration; Discussion that appears across unrelated shows, distinct speakers, and varied formats may possess broader social reach. Discussion confined to closely linked hosts and guests may be better interpreted as a local narrative cluster.
Production quality complicates the measurement of attention. Research on spatial sound identifies renewed interest in immersive practices while documenting cultural and production barriers to wider adoption in podcast and radio work. [9] The reasonable inference is that identical words may reach listeners with different emotional force when production styles differ.
A transcript-only model may miss that variation; A model weighted heavily toward delivery may overfit it. The challenge is not choosing text or sound; it is testing whether either representation adds measurable value beyond the other.
This creates a natural division of labor. Machines can process speech, preserve timestamps, calculate repeated features, and identify unusual changes. Analysts can decide whether a detected shift reflects a meaningful economic development, a promotional cycle, a guest-booking coincidence, or a burst of attention.
The strongest near-term use may be research triage; A system could rank episodes for review, identify recurring themes, map repeated claims, or monitor changes in confidence around defined subjects. That is less dramatic than a fully automated portfolio, but it is more consistent with the available evidence.
There is also a possible portfolio-risk application. The cited sentiment research links changes in both structured and unstructured sentiment with market volatility, with a stronger unstructured-sentiment volatility effect when noise-trader participation is higher. [24] A podcast-derived index could be tested as one component of a broader framework for identifying periods in which narrative sensitivity deserves greater caution.
The key phrase is “could be tested;” The ledger does not establish that podcast sentiment predicts market volatility, returns, factor spreads, or security-level outcomes. Any stronger claim would exceed the evidence.
Participation introduces another implication: feedback. Social-podcasting research examines varying levels of audience participation, showing that a podcast can become part of an interactive communication process. [22] In an investing context, hosts, audiences, clips, sharing, and later commentary may create a loop.
Such loops may matter only if they can be measured before prices adjust and only if they are not simply reactions to market moves already underway; That is a demanding evidentiary standard. A credible system must test whether audio changes lead, lag, or merely accompany the variables it seeks to explain.
KEY TAKEAWAY: The most defensible use for podcast sentiment is as a monitored regime, attention, and research-prioritization input—not an unsupported stand-alone trading oracle. [22][24]
Editorial figure: The report's market-transmission and investment logic rendered as a visual framework; the illustration does not represent measured data.
The Competitive Field
The competitive field is difficult to map from the available evidence. The ledger verifies research topics and organizations, not a mature universe of public, directly investable podcast-sentiment vendors. That absence is itself analytically important.
A credible map separates four functions: audio capture and security, source separation, language interpretation, and investment implementation. No ledger item verifies a public company that owns all four functions or captures the full economic value of the theme.
| Company | Ticker | Market Cap | Key Metric | Vetta Signal |
|---|---|---|---|---|
| Google Research | Not verified | Not verified | Contrastive neural audio separation research [7] | Research relevance, not a verified security signal |
| Kaspersky | Not verified | Not verified | InjectEave audio-interception attack reference [1] | Security-diligence relevance |
| Podcast and radio production sector | Not verified | Not verified | Spatial-audio adoption barriers in factual programming [9] | Data-quality and format-risk relevance |
Potential positive infrastructure impact
Google Research appears in the ledger through contrastive neural audio separation research; [7] Its relevance is technological: audio systems need credible methods for distinguishing sources and reducing interference before higher-level inference can become useful.
The ledger does not provide a public ticker, market capitalization, revenue exposure, or verified link to podcast-sentiment products. It therefore cannot support a LONG, SHORT, or WATCH designation. The research relevance should not be converted into a security thesis by implication.
The possible positive implication lies in the infrastructure problem; Better separation may improve downstream speaker attribution, transcript quality, and context preservation. Yet improvement in a technical layer does not prove that a market-facing signal will be predictive, scalable, or economically valuable.
Negative implementation and standardization impact
Kaspersky appears through the InjectEave reference concerning interception of analog audio signals. [1] Its relevance is not that it is a verified beneficiary of podcast analytics. It is a reminder that audio systems require threat modeling, integrity checks, access controls, and clear assumptions about what was captured and transformed.
The production sector appears through research on spatial audio’s revival and its constrained adoption in factual radio and podcasting; [9] For a sentiment model, this is a negative signal for standardization. Heterogeneous production practices can widen the gap between a transcript’s literal wording and an audience’s experienced meaning.
The lack of a clean public-equity map should make investors more selective, not more imaginative. Emerging themes can tempt analysts to assign thematic exposure to recognizable technology names without proving the revenue link, data advantage, or economic capture. The ledger does not justify that move here.
The competitive question should instead focus on bottlenecks. Raw audio access may be available from many sources. Transcription may become easier to obtain. Generic sentiment scoring may also become widely available.
The harder layers may be provenance, domain-specific labeling, longitudinal speaker histories, and validated links between model outputs and economically relevant decisions. This is an inference from the pipeline requirements, supported by the distinct challenges documented across audio separation, sound recognition, production design, and unstructured sentiment. [2][7][9][24]
An audio-intelligence platform without proprietary ground truth can become a mirror of public language; If many models listen to the same popular programs and produce similar sentiment labels, the outcome may be crowded consensus rather than differentiated insight.
The opposite danger is narrowness. A dataset dominated by one geography, political orientation, host network, or production style may produce precise-looking scores that do not generalize. Precision in measurement is not the same as breadth in representation.
Competitive durability therefore depends on measurement discipline more than the novelty of listening to podcasts. A durable system would require auditable sourcing, stable speaker resolution, defensible topic taxonomy, rigorous testing, and a documented method for removing contaminating segments.
The cost is equally real; Each additional control adds complexity: separating audio, assigning speakers, validating claims, preserving provenance, and monitoring drift can turn a lightweight alternative-data concept into a labor-intensive research operation.
A system requiring substantial human verification may offer high-quality research support but poor scalability. A system that removes human review may scale rapidly while compounding hidden classification error. The ledger does not establish which trade-off any named company has solved.
Investment Thesis
The investment thesis is deliberately narrow: the sonic-alpha opportunity is credible as a research category, but unproven as a direct security-specific investment thesis.
Its foundation lies in the distinction between structured and unstructured sentiment. The cited research finds relationships among sentiment, returns, and volatility, including a stronger volatility effect from changes in unstructured sentiment when noise-trader participation rises. [24] That gives systematic investors a reason to investigate unconventional expressions of belief.
Podcast audio is one such expression; It combines language with vocal delivery, timing, production context, and social distribution. Its potential advantage over text-only sentiment is not privileged access to hidden truth.
The bull case rests on incremental information; If a disciplined system can isolate relevant speech, distinguish speakers, identify topic-specific discussion, and demonstrate out-of-sample value beyond transcript-only and structured-sentiment controls, audio features may improve a multi-signal framework. [7][24]
The bear case rests on contamination. Podcast recordings may contain non-investment language, showmanship, editing, advertisements, and social incentives that distort interpretation. Production variation and spatial-audio differences further weaken the assumption that all episodes are comparable measurement objects. [9]
Conviction should remain exploratory, not high; The ledger supports the theoretical relevance of unstructured sentiment and the technical reality of audio-processing challenges. [7][24] It does not support a verified podcast-sentiment backtest, commercial adoption curve, direct revenue pool, or investable company exposure.
Valuation limits are absolute under the available evidence. No market capitalization, enterprise value, revenue multiple, earnings estimate, ticker, or options listing is provided for a directly exposed security. A valuation framework would require unsupported inputs.
Catalysts are research catalysts rather than stock catalysts. Credibility would improve if a model demonstrated incremental value after controls, maintained results out of sample, survived changes in show composition, and showed that its signal was not merely a delayed reaction to market movement.
Invalidation conditions should be equally direct; The thesis weakens if audio features add no information beyond transcripts, results vanish after source-level controls, performance concentrates in a small number of episodes or speakers, or outputs cannot be audited to identifiable source segments.
Implementation risk remains high. The route from an episode to an investment decision requires ingestion, separation, speaker attribution, contextual interpretation, validation, governance, and portfolio integration. Failure at any layer can turn apparent insight into a polished form of noise.
KEY TAKEAWAY: The investable claim is not that podcasts forecast markets, but that validated audio features may improve a broader unstructured-sentiment research stack. [7][24]
Challenges & Risks
The first risk is semantic overreach; Sentiment is not forecast accuracy, and emotional intensity is not investable conviction. A speaker may sound certain while being wrong, uncertain while being correct, or dramatic because the format rewards attention.
The second risk is representation. A transcript removes elements of delivery that may affect interpretation, while acoustic features introduce their own fragility. The system can become trapped between text that is too flat and audio that is too context-sensitive.
Audio separation matters because recordings may contain overlapping sources; Google Research’s work on contrastive neural audio separation indicates that disentangling audio components is a meaningful technical challenge. [7] In podcast material, residual music, crosstalk, remote-call artifacts, or misidentified speakers can contaminate downstream labels.
The third risk is source bias. Podcasts are not necessarily a representative sample of investors, consumers, executives, or the public. They reflect who has access to microphones, who gets booked, what audiences prefer, and what producers decide to distribute.
A model may therefore learn the preferences of a vocal subset rather than broad market belief; This is particularly dangerous when a scoring system appears comprehensive because it processes many hours of audio while drawing from a narrow social base. Scale does not automatically cure selection bias.
The fourth risk is feedback contamination. If a podcast responds to a market move after it occurs, the model may appear insightful while merely encoding price-following commentary. Proper testing must establish timing and control for prior returns, volatility, news, and textual signals.
The ledger does not provide a podcast-specific causal result. Causality should therefore not be presumed from the general finding that structured and unstructured sentiment relate to returns and volatility. [24]
The fifth risk is privacy and ethics. Research on immersive audio identifies privacy, accessibility, and psychological impact among the ethical issues connected to audio design. [14] Public availability of an episode does not resolve concerns about deriving behavioral or emotional profiles from voices at scale.
The sixth risk is security; The InjectEave reference concerns interception of analog audio signals. [1] It does not demonstrate compromise of a podcast-analytics platform, but it reinforces the need for data provenance, controlled ingestion, and integrity checks.
The seventh risk is false precision. A score reported to two decimal places can imply scientific certainty even when it rests on uncertain speaker labels, unclear topic boundaries, and uneven source quality. Numerical form should never substitute for proof that a measure captures what it claims to capture.
The eighth risk is regime dependence; The cited investor-sentiment work links sentiment changes to volatility and identifies a stronger unstructured-sentiment effect under greater noise-trader participation. [24] At minimum, that suggests the relation between unstructured expression and market behavior may vary with market conditions and participant composition.
The ninth risk is commercialization before validation. Searchable transcripts, elegant dashboards, waveform displays, and automated summaries may improve workflow without improving returns or risk control. A compelling interface can make an uncertain signal feel more established than it is.
The tenth risk is model drift. Podcast formats change. Hosts change. Guests may adapt to measurement. Production practices evolve, and audience behavior may shift as distribution systems change.
For these reasons, the risk framework should include human review, source-level audit logs, benchmark comparisons, version control, and explicit kill criteria. The process must be willing to conclude that audio adds no investment value.
That conclusion would not mean the technology failed; It would mean the investment hypothesis did not survive contact with evidence.
The Investment Angle
The investment angle begins with restraint. There is no ledger-supported basis to recommend a public security as a direct LONG, SHORT, or WATCH expression of podcast sentiment scoring.
That limitation shifts implementation from security selection to research architecture; The most credible approach is to treat podcast sentiment as a candidate alternative-data feature and apply the same discipline required of any other signal.
First, define the economic question. A model may seek shifts in retail attention, sector narratives, macro uncertainty, or disagreement among recurring speakers. It should not begin with a generic instruction to identify “bullish” or “bearish” episodes.
Second, define the source universe; Selected shows should have a documented rationale, stable access method, and explicit inclusion rules. A broad universe may improve coverage while reducing consistency; a narrow universe may improve interpretability while increasing sampling bias.
Third, construct a transcript-only benchmark. This is essential because the incremental proposition is not that speech contains words. It is that audio representation may add information beyond the words.
If a transcript model performs equally well, acoustic complexity may not justify its cost; The mixing desk has no virtue if turning more knobs does not improve the sound. Complexity should earn its place through evidence.
Fourth, introduce audio features cautiously. Pauses, turn-taking, overlap, vocal energy, and delivery changes may be candidate features, but each should remain a hypothesis rather than a discovered fact. The ledger does not validate any specific prosodic feature as a financial predictor.
Fifth, test against structured sentiment; The cited research explicitly distinguishes structured from unstructured sentiment. [24] A podcast score should therefore be evaluated against market outcomes and against relevant structured measures available within the investor’s own research process.
Sixth, test stability. A useful feature should not depend on one famous host, one extraordinary market episode, or one narrow thematic burst. Removing dominant shows and repeating the analysis can reveal whether the signal is diversified or merely celebrity-weighted.
Seventh, choose the implementation horizon; A slow-moving research measure may be better suited to thematic monitoring, risk discussion, and analyst prioritization than rapid execution. The desire for intraday novelty should not outrun the pace at which episodes are published, processed, and absorbed.
Eighth, create an exception process. Scores should be reviewable at the source level. An analyst should be able to inspect the segment, identify the speaker, understand the context, and determine whether the model confused an advertisement, joke, quotation, or serious claim.
Ninth, separate commercial benefit from trading benefit; A firm may benefit from selling transcription, search, analytics, or workflow software even if no audio-derived trading factor proves durable. The ledger does not identify a public company with verified exposure to such revenues, so that distinction cannot become a stock thesis here.
Tenth, omit options implementation. Listed-options availability is not verified for any direct beneficiary or relevant security in the ledger. No options spread, hedge, or derivatives structure should be inferred.
The practical expression, if any, is indirect; A marked rise in topic-specific uncertainty might prompt deeper fundamental work, tighter scenario analysis, or a review of crowding assumptions. It should not mechanically force a trade without corroboration.
This approach respects the core evidence; Unstructured sentiment may matter for returns and volatility dynamics, but the route from a spoken episode to a tradeable decision remains long and technically exposed. [24]
The soundest implementation is not a black-box bet on voices. It is a measured effort to learn whether those voices improve the investor’s existing map of market belief.
Future Outlook
The future of sonic alpha will depend less on whether machines can hear and more on whether investors can define what listening should accomplish.
Audio research shows that sound can be separated, recognized, and analyzed across varied contexts. Contrastive neural audio separation points to work on isolating components within recordings, while sound-signal studies in mechanical and underwater settings illustrate the breadth of acoustic-recognition problems. [2][7][8]
These developments support technical possibility, not a guaranteed financial application. The distinction may seem modest, but it is the line between research and promotion. A machine’s ability to detect a pattern does not establish that the pattern deserves capital.
Podcasting may remain a meaningful source of unstructured expression because it supports specialized subjects, flexible consumption, participation, and evolving monetization approaches. [11][22] Those qualities make the medium expressive, but they also make it inconsistent.
More content can increase coverage. It can also create more duplication, more promotional material, more source bias, and more opportunities for narrative contagion. The accumulation of audio does not automatically create a cleaner measure of belief.
Immersive and spatial-audio work adds another complication; Audio may become richer as production methods evolve, but richer presentation does not automatically create cleaner data. Research identifies revived interest in spatial sound alongside persistent barriers to its use in factual podcast and radio production. [9]
Future systems will need to decide whether production variation is noise to remove or context to model. That question has no universal answer. It depends on whether delivery changes the economic meaning of a statement or merely changes its emotional packaging.
The most promising research direction is multimodal comparison; A future study could compare transcript-only sentiment, acoustic-feature sentiment, episode metadata, speaker-history variables, and structured sentiment measures. The objective would be modest but meaningful: determine whether each layer contributes distinct out-of-sample information.
Another promising direction is disagreement measurement. Rather than asking whether a show is positive or negative, a system could measure whether recurring speakers are converging, diverging, becoming more conditional, or repeating a shared narrative. Such measures may capture uncertainty better than a single average sentiment score.
A third direction is provenance-first architecture; As models become more capable, the premium may shift toward systems that can explain where a score came from and why it changed. A transparent output that points to a timestamp, speaker, topic, and confidence range may be more useful than an opaque model with a dramatic headline number.
The long arc of this idea is contemplative rather than triumphant. Markets have always listened to stories. Podcasts make more stories machine-readable, but readability is not reliability.
The signal will earn a place only if it survives the full sequence of separation, interpretation, validation, and implementation; In that sense, the opportunity is not to make markets louder. It is to make research more discerning about which voices deserve to change the score.
Sources & References
- Kaspersky. "InjectEave: an attack that intercepts analog audio signals - Kaspersky." Tue,. https://news.google.com/rss/articles/CBMieEFVX3lxTE9nWEVwd2VXckNydi1VZmViZlNmQmJwVW9rUkc0MzNiZ0dzekdsMndWNUttenZDWTdOX1NCakdPR0VkX0dobHZ3TFpodHNrd185MlR4SEJrSHR2Wjc5LTF5Y196ZlgxYU9YVXdZT1Q1QjdJMU4yRTlFZA?oc=5
- Science Partner Journals. "High-Performance Iontronic Hydrogel Acoustic Sensor for Low-Frequency Underwater Sound Detection and Intelligent Recognition - Science Partner Journals." Fri,. https://news.google.com/rss/articles/CBMiX0FVX3lxTE0tbDRSYkVzRGNWUk1BZzh2RnZ5ci16S18xRXNfZG1Wb3lrR01QZ2xhMkVRcWl0REJyOE85dFpuWTY4VlZKaHdzSk5wb1JtYWNrbVRZTzBHOUZtUElHVEJJ?oc=5
- USA Today. "The 33rd Frequency Reviews: Releases Daily Audio Program for Relaxation and Stress Reduction With Component-by-Component Research Overview - USA Today." Thu,. https://news.google.com/rss/articles/CBMimAJBVV95cUxOYjhsaTZmenFWamdqZ21seDlwVUFELU9VamdTZEs0eXJFbGJOVUJZNTRBbXZvRnkteXpxTDJFTUYwOG8tamlIQWt4RGdfYjRTX2poWEJ2M3pPb2Z6MG9lOGQ2ci15WFgtbWplUW1FX2V0bFJCYTB4NVdNdlJWQWtKdnJKdWFmcGZSdFpLNnQ0bG5ZdWRiUWxIdkNlWHBDVllRc1pZRVVPekFfWnNBNVJHS2doWEtvZDFaTG11ZHo5a2h2NkExdTRQREIyaFJnMHlsUFlJcGtnUHZYWmJXZ182ZkJhY2JNX1FRbnBNbUtvOUw3MUdhTWNEZWVzZ3Z1UVIzZTRWNFZyYzEyOWRpX1FIaWNWYmVXSkpT?oc=5
- EurekAlert! Science News Releases. "Mixed signals: Machine learning helps detecting roars from lion collars without recording actual audio - EurekAlert! Science News Releases." Wed,. https://news.google.com/rss/articles/CBMiXEFVX3lxTE5xcXVqT2FlSHROaUtxbEcyZ3FGUDhUUzBjbzRyVDRxTkpQeTZsc3VmS1NWVEVvbXdJS0F5b1o0OXF0ZU9ReHZMVUdBazR1UlBnRlNfd3NRVGZzTDIz?oc=5
- Interesting Engineering. "US researchers discover hidden tunnels with underground sound waves - Interesting Engineering." Fri,. https://news.google.com/rss/articles/CBMiygFBVV95cUxQZ01kOUZzcnc3TDltbmhkdENaUWtPUURZT214YlYzSENxYnVRcGpPX2RrSDMyVTAyRE91ck55dzB6WUJzWWROVTNwLUxKOWdWemc1eEpxRlBJa25fX1FEWjd1TjFLWDN1Z253OXJCQ1JMLWltSEZFNlBHV1pEUWlQMTFzYzRQdEZDdS01UHl2bDkxbWFWcWRIUVc5eFhWZUh0VWhTUXRZQXpLaDI5c2ZwSkg1cktwMVhkN2d1NHJGUVNOSHlQeDNGX05n?oc=5
- Neuroscience News. "People Who Hear "The Hum" Are Facing Low-Frequency Tinnitus - Neuroscience News." Tue,. https://news.google.com/rss/articles/CBMib0FVX3lxTE42NFBtcWxxNUxHMnZpbzdLeXNxeHBDRWdVdWV4Mm9idHV6WnBUb1RLd0RqMDVFMDBMZGtwODNUeFpZRG1wYzE0OWdTV0FxMGl3M2MySk0tZkVFanJNOWhXV0dsd0IzZFlndHNHTXVSZw?oc=5
- Google Research. "Contrastive neural audio separation - Google Research." Fri,. https://news.google.com/rss/articles/CBMic0FVX3lxTE1pUGxPNl9TS21DYnhCdWhlTU42Ti1TZzB3cUQtZ1NmMGJxRDdJRnBQRkJJbjVvd01rOVE1NGlfdWdUOXAwZ2NzTGZqT3NRZDEzeURLNVBCSlI2YkxZZ1FEYWNBYnNfWkk5UERxWWVEM0NaQkE?oc=5
- Nature. "Research on bolt loosening recognition based on sound signal and GA-SVM–RFE - Nature." Mon,. https://news.google.com/rss/articles/CBMiX0FVX3lxTFBmVk5nZVBtZzVPTlp0U3ZRTmsxaVVpMTcyWVRZVmRteGQ5QXVMejI3bXZUVlR3MlRINmM3Yi02aEtKS2VHV2ZBay14bTdlOE0xYUZZSmdjQlQ2UDJtWEtv?oc=5
- Radio Journal:International Studies in Broadcast & Audio Media. "Why don’t more journalists and documentary makers use spatial audio? Barriers to sonic experimentation in contemporary radio and podcast production cultures." 2025. https://doi.org/10.1386/rjao_00121_1
- Journal of Sonic Studies. "Warbound: Collective Audio Streaming from Ukraine." 2025. https://doi.org/10.22501/jss.2796403
- NIVEDANA : Jurnal Komunikasi dan Bahasa. "REVOLUSI AUDIO DIGITAL: TANTANGAN RADIO DI TENGAH GELOMBANG POPULARITAS PODCAST." 2024. https://doi.org/10.53565/nivedana.v5i3.1285
- Sonic Scope. "Phantasy and Illusion: Audio Unconscious in Creative Sound Practice." 2024. https://doi.org/10.21428/66f840a4.da53b2b7
- The Sociological Review Magazine. "Space Invaders [Audio podcast episode]." 2023. https://doi.org/10.51428/tsr.tujy3065
- Connessioni remote. Artivismo_Teatro_Tecnologia. "Sonic Landscapes in the Metaverse: Exploring Immersive Audio Design in Virtual Environments." 2024. https://doi.org/10.54103/connessioni/26755
- The Sociological Review Magazine. "Geographical Imaginations [Audio podcast episode]." 2023. https://doi.org/10.51428/tsr.uylj6693
- The Society for Music Theory Podcast. "Sonic Identity Imitation and Critical Listening in Popular Music." 2022. https://doi.org/10.30535/smtpod.1.5
- Educational Action Research. "Podcast Review: The Action Research Podcast." 2022. https://doi.org/10.1080/09650792.2022.2106261
- The Sociological Review Magazine. "World City [Audio podcast episode]." 2022. https://doi.org/10.51428/tsr.orqi7190
- The Sociological Review Magazine. "Invasión Espacial [Audio podcast episode]." 2023. https://doi.org/10.51428/tsr.msbf5807
- The Sociological Review Magazine. "Political Engagement [Audio podcast episode]." 2023. https://doi.org/10.51428/tsr.ymrh4796
- Jurnal Kesehatan Siliwangi. "MEDIA EDUKASI AUDIO PODCAST DIET SEIMBANG SEBAGAI UPAYA PENCEGAHAN DIABETES MELITUS TIPE 2." 2024. https://doi.org/10.34011/jks.00.2519
- Journal of Radio & Audio Media. "Social Podcasting - Levels of Podcast Audience Participation." 2025. https://doi.org/10.1080/19376529.2025.2460834
- The Sociological Review Magazine. "Why Stigma? With Michaela Benson [Audio podcast episode]." 2023. https://doi.org/10.51428/tsr.qxir7539
- International Review of Finance. "Unpacking the black box of investor sentiment: Structured sentiment and unstructured sentiment." 2023. https://doi.org/10.1111/irfi.12440
All sources were verified at the time of publication.
Disclaimer: The information provided in this article is for educational and informational purposes only and does not constitute investment advice, a solicitation, or a recommendation to buy or sell any security; Vetta Investments does not guarantee the accuracy, completeness, or timeliness of any information presented.
Past performance is not indicative of future results. All investments involve risk, including the possible loss of principal. Readers should conduct their own due diligence and consult a qualified financial advisor before making any investment decisions. Vetta Investments may hold positions in securities mentioned in this article.